Your assistant gives poor answers
It retrieves the wrong passage, cites an old version or answers without a source.
We assess your sources, prepare your documents and build retrieval for your AI tools. You receive documented architecture, governance rules and a knowledge base evaluated against your team’s questions.
It retrieves the wrong passage, cites an old version or answers without a source.
The same information lives in document systems, tickets, shared files and business tools.
Updates, permissions, costs and maintenance have not been addressed.
Each stage can be commissioned separately. The proposal specifies sources, connectors, volumes, responsibilities and acceptance criteria.
Decide where to invest and what to start with.
Decision: an agreed scope, business owner and success criteria.
Build the pipeline from source content to useful context.
Decision: the right users can retrieve the right sources.
Check reliability and organise operations.
Decision: agreed thresholds are met, or limitations are explicit.
Recurring operations, licences, model calls and business-agent development are costed separately. A pilot scope tests design choices; it does not replace governance across the full data estate.
A terabyte of files does not map directly to tokens. Retrieval selects relevant evidence for a question; access rules are applied before passing it to the model.
Document systems, files, tickets and business exports: scope and permissions checked.
Text, tables, versions, metadata and provenance retained.
Keywords + semantic search, filters and passage ranking.
Authorised context, inspectable references and abstention when needed.
Retrieval-augmented generation (RAG) is an option, not a requirement. For structured numerical data, a controlled query or calculation can be preferable to retrieving text passages.
We test native PDFs, scans and tables on a representative sample. Unreadable documents are quarantined with an explicit reason rather than silently ignored.
Check: processing coverage, extraction errors and corpus coverage.
Each document has an identifier, source, owner, validity date, version and classification. Chunking preserves headings, page references and links to the original.
Check: retrieve the applicable version and its provenance.
We compare keyword, vector and hybrid search against your questions. Reranking is added if it improves quality at an acceptable cost and latency.
Check: expected evidence appears in the first results (Recall@k).
We model users, groups and document permissions. Filters apply during retrieval; a prompt instruction is not an access control.
Check: cross-role tests, permission revocation and forbidden sources.
The pipeline detects new, changed and deleted documents. Failed processing can be resumed and content reindexed after schema or embedding-model changes.
Check: freshness delay, deletion propagation and no stale ghost versions.
We build questions with expected answers and evidence, validated by business users. Tests also cover conflicting documents, out-of-scope questions and malicious instructions inside source content.
Check: supported citations, accepted answers, appropriate refusals, p95 latency and cost per query.
Across 400 requests a month, reducing search time from 12 to 7 minutes frees about 33 hours. This is a hypothesis to test; verification time, maintenance and service costs must be deducted to calculate net benefit.
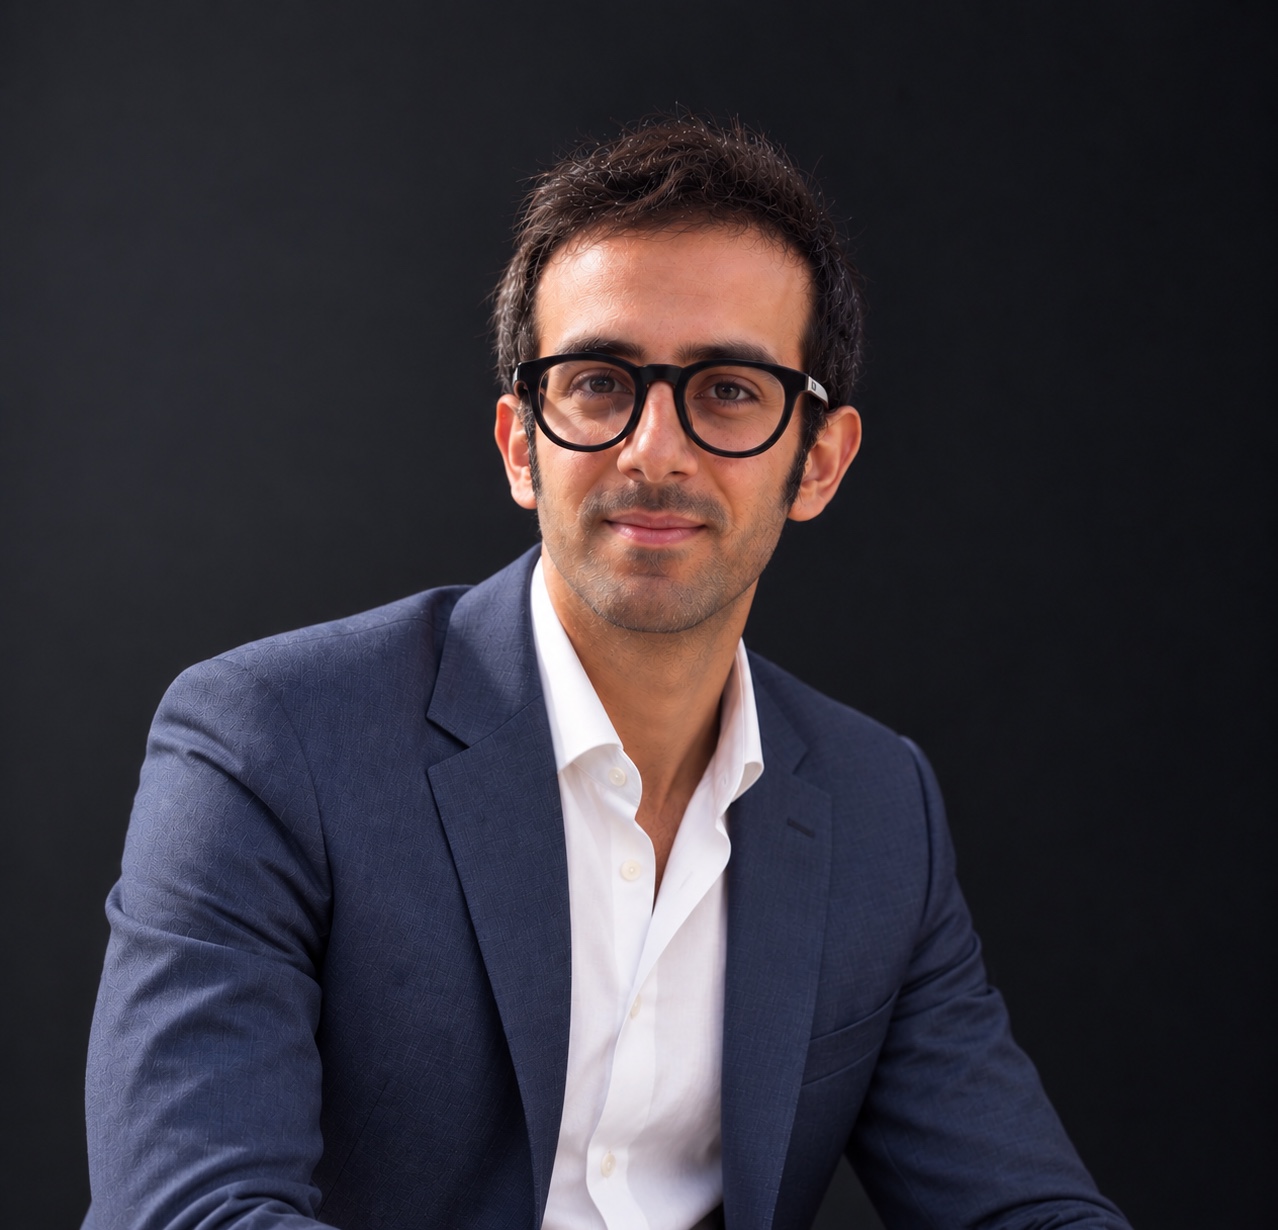
Your Mintera Knowledge lead
Data & AI value creation · 8 years at Sopra Steria
Benjamin brings eight years of experience at Sopra Steria and expertise in data challenges and creating value with AI. At Mintera, he is your lead for connecting business requirements with data preparation and integration choices.
His role on your project: challenge the scope, assess sources, define quality criteria and coordinate technical decisions with your team.
Discuss my project with BenjaminTell us about your tools, relevant data and desired outcome. We will define the work needed and a scope that can be priced.